
I’ve been in the data world for decades, and saying that out loud is a bit unnerving. Over the years I’ve fought against all kinds of rigid standards for how data is supposed to be handled. Whether it’s RDBMS, OLAP, TSDB, NoSQL, tuples, graphs, or whatever new acronym comes along next. It’s not the technologies themselves that I push against. It’s the rigidity of the thinking behind them and the polarization within the technology industry around how data should be organized, stored, accessed, and governed, often without an innate understanding of the true nature of data itself.
If you don’t know half those acronyms, you’re probably better off.
Every time we turn around, the technology industry packages up another approach and insists that this time they’ve finally cracked it. This time your data will be clean, unified, accessible, and governed. Suffice to say, all these technologies have a place and serve a purpose, but none of them have cracked it. Not even close.
Most of these systems are fundamentally about data storage and persistence. They provide different ways to organize, retrieve, and manage data, but they don’t really address how information is processed and used throughout a business, within applications, across connected systems, and especially in the world of AI. My perspective has always been rooted in the processing of data, not necessarily the storage of it.
In processing, data is use-dependent and moves through composite streams that are constantly being transformed. Analytics is one form of processing, but it’s largely retrospective and isolated from the actual execution of the business. Most enterprise applications have also operated within relatively well-defined processing boundaries, even if the data underneath them is fragmented and at times downright chaotic.
The most consequential change today is agentic AI, where the processing is continuous, context is constantly changing, and the systems consuming the information can make decisions and take actions on their own. That introduces a very different problem from simply managing data. And watching the industry struggle to recognize the distinction has been frustrating, to say the least.
Security in the Agentic AI world is still fixated on use-independent legacy controls. It needs to shift to use-dependent where context competence, adaptive policy enforcement, and runtime controls are essential.
The Legacy Trap
Unfortunately, it appears that everybody in the data and security worlds has retreated right back into their comfortable corners. The familiar world of stored data and how to protect it. Encryption at rest, firewalls, proxies, RBAC and ABAC controls, and siloed, purpose-built repositories. All perfectly legitimate technologies, but the underlying thinking is still rooted in controlling data according to where it lives, how it’s classified, and who is allowed to access it.
When I look across enterprises today, I find almost everyone landing in one of three camps. First, you have the structured database folks who think the universe begins and ends with row and column permissions in Snowflake, Databricks, or Postgres. Then you have the document folks living in SharePoint and Box, convinced that security means applying sensitivity labels to files and folders. Finally, you have the data science folks who seem to think everything revolves around vectors, token embeddings, and cosine similarity, with data governance being an annoying problem that belongs to whoever sits upstream.
I realize that’s a broad generalization, but enterprises really can be that polarized. The business side versus the technology side, security versus operations, and everyone sitting in their own silo assuming their view of the world holds.
Even the discussions around AI data processing often wander off into training data, model quality, and preparing datasets. Those are important problems, but training a model and governing the information being processed by that model during live execution (inferencing) are two entirely different things. It’s astonishing how often those discussions get conflated, including among people who should know better.
The Wrinkle
The wrinkle in all of this is that data being processed by an agentic system doesn’t respect those convenient boundaries. It’s moving between systems, being interpreted, combined, transformed, and used to make decisions, all at runtime. What started as a perfectly ordinary database record can become part of an entirely new piece of information that didn’t previously exist. That information may then be passed to another agent, combined with something else, and used to initiate a transaction. At each stage, the context, meaning, and permissible use of that information can change, even though the original sources haven’t changed at all.
And yet security in the agentic world is still largely fixated on use-independent legacy controls. We’re protecting the repository, authenticating the API request, and checking whether an identity has access to a particular resource. Those controls remain necessary, but the protection of information being processed in real time needs to be use-dependent. The context of the operation, the authority under which it’s happening, and the intended outcome all matter. That’s where context competence, adaptive policy enforcement, and runtime controls become essential, and it’s a very different way of thinking about data protection.
Flashbacks and Data Swamps
To be honest, watching this unfold gives me serious flashbacks to the early days of the data lake. Remember when everyone bought into the dream of dumping raw files, transaction logs, and unvetted records into cheap object storage? Hadoop, anyone? The big pitch was schema on read. Don’t worry about structuring it now, just throw everything into the lake and we’ll figure the schema out later. From ETL to ELT to who knows what. We all know how that story went for a lot of organizations. Billions of dollars spent and companies ended up with toxic, unsearchable data swamps that nobody could adequately audit, govern, or clean up.
The Snowflakes and Databricks of the world are fine. They’re extremely useful technologies and perfectly reasonable places to start, even if they haven’t cracked it.
The challenge is that the technology industry is selling a remarkably similar dream today, except instead of schema on read, we’re getting reasoning on context. Just connect your databases, vector indexes, file shares, and APIs to an agent framework and let the AI model figure it out. On the flip side, there’s this massive push by data pundits to make your data “AI-ready,” which is another form of déjà vu for me. Ready for what? Prepared how? For which agent, operating under whose authority, making what decision, using which information, and at what point in time?
I’m not suggesting data quality doesn’t matter … of course it does. But if you believe that cleaning up your datasets and connecting them to an LLM solves the information-processing problem, you’re missing an enormous part of what’s actually happening. The same mistakes are being repeated, only this time the swamp is running live.
The Data Stream
Here’s where I believe the industry has data wrong. We’re still talking about data as though its structure, or lack thereof, is the defining characteristic. Structured, unstructured, semi-structured, whatever category happens to fit the technology we’re using. Those distinctions tell us something about how information is represented and stored, but remarkably little about what happens when that information is actually being processed.
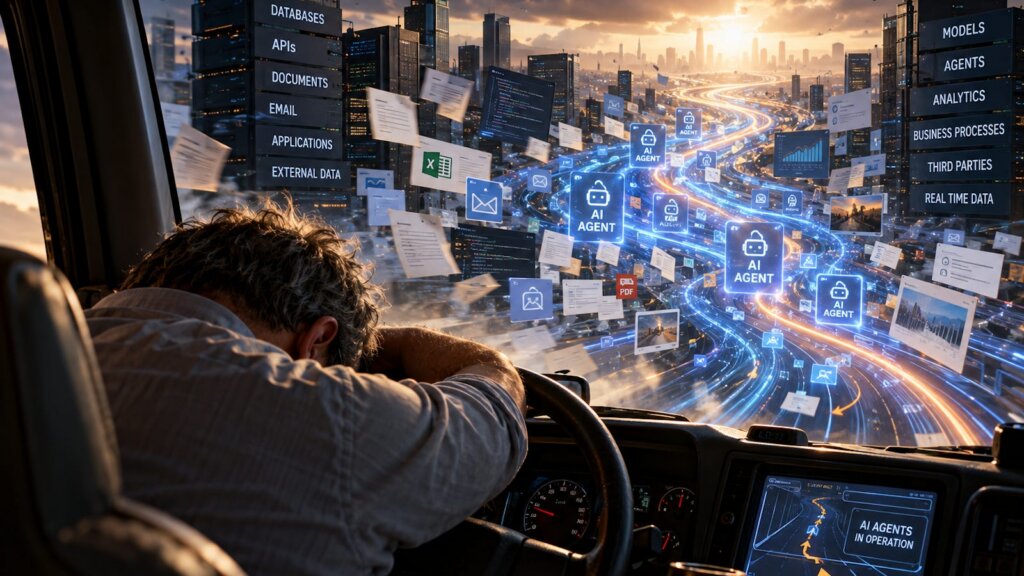
In an agentic system, what we’re dealing with is a composite stream, not a streaming architecture but a continuous flow of information. A clean, structured set of data gets retrieved from a relational database. An email contributes some additional context. A document provides a contractual obligation. A vector search returns related information, another agent contributes an intermediate conclusion, and an API provides a JSON payload. All of this gets assembled, interpreted, and processed by a model that produces something new. That output becomes part of another stream, perhaps feeding another agent, another model, or an execution tool. The resulting information might be represented as text, bytes, tokens, vectors, or structured payloads at different stages, but its original storage format doesn’t tell you how it should be protected or whether it can legitimately be used.
A JSON payload doesn’t change any of that. It just packages up information in pretty brackets. You can define the schema and validate every field, but that doesn’t establish whether the information is correct, whether the combination is permissible, whether the receiving agent has authority to use it, or whether the resulting action is legitimate. The structure is useful for processing, but it isn’t a substitute for understanding what is being processed.
This is why I keep coming back to the composite stream. Information is constantly entering and leaving models, passing between agents, being transformed and producing new information along the way. It’s not simply a prompt that needs protection, nor is it merely a collection of source documents with static sensitivity labels. It’s a living processing environment where information takes on new meaning depending on how it’s combined, why it’s being used, and what the system intends to do with it.
So how do you protect that stream when its sources are scattered across your organization and beyond? Do you centralize everything in a repository and encrypt it? Put it all into a lakehouse and apply static classifications so PII doesn’t leak? Lock down the models and insist that no unencrypted information can leave the building? Those approaches may address particular requirements, but none of them answers the larger question of what happens to information as it moves through the execution of a business process … especially one that is federated across departments, divisions, subsidiaries, partners, customers, clients and intermediaries.
A Use Case
This conundrum isn’t new, just as AI isn’t new. People have been banging their heads against information-processing problems for decades. Consider client onboarding, which has to be one of the most troublesome and painful business processes in existence. An enterprise wants to sign a new client. Forms get filled in, messy documents get handed over, records are pulled from registries, databases are searched, credit checks and KYC checks are performed, and every detail needs to be verified before anything gets committed to a proprietary, internal, system of record.
That process is exhausting, and the information involved is anything but neat and tidy. We’re dealing with PDFs, emails, credit reports, transaction histories, operational tables, external services, and information supplied by people who may or may not have their facts straight. An agent (or agents) processing all of that information needs to make sense of it in the context of the business process, and what emerges is a composite stream of information assembled from multiple sources with different levels of sensitivity, reliability, and authority.
Knowing what constitutes PII is relatively straightforward these days and almost trivial. The more interesting problem is understanding which transactional details are sensitive, what can be shared, and who gets to share it. Which division, person, or agent inside your company has clearance for what? What can be disclosed to an underwriter or third-party agency? What happens when the information is perfectly legitimate for one business purpose but prohibited for another?
And when that information gets mashed up with internal records to produce a new conclusion, how do you establish that the processing itself was authorized, and how do you go about protecting the outcome?
There’s a tendency to treat this as a data-access problem, but access is only the beginning. The information may have been retrieved legitimately from every source involved and still produce a result that shouldn’t be used or disclosed. Cross-referencing sensitive information can itself introduce compliance and privacy problems, and the fact that every individual retrieval was authorized doesn’t necessarily make the resulting processing legitimate.
Composite Data & Mashups
In loose terms, I think of this as the era of Mashup 3.0, and it’s where the comfortable assumptions about data management start getting particularly dangerous.
In the early web days, a mashup was wiring two APIs together to put listings on a map. In the BI era, it was an analyst blending an ERP table with a Salesforce export in Tableau. Those processes could be annoying to manage, but the relationships were largely deterministic. Somebody had to pick the keys, define the fields, write the logic, and decide what the resulting information meant. There was generally humans involved somewhere in that process, even if the resulting application operated automatically.
In Mashup 3.0, the agents are assembling information on the fly, using semantic interpretation, retrieved context, tool responses, and intermediate conclusions. It can establish relationships between information that nobody explicitly defined beforehand. Some of those relationships will be useful, some will be wrong, and others may be perfectly reasonable conclusions that the agent was never authorized to derive or disclose in the first place.
You are seeing this play out in real time as frontier labs hack and break down firewalls.
Protecting data inside a database solves a particular static use case. The moment that information is retrieved and made available to an agent for processing, the problem changes. The database thinks it did its job because it logged an authorized read. The document repository thinks it did its job because the requesting identity had permission. The API gateway is happy because everything was authenticated. Everybody did their job, at least according to the controls (not necessarily the use-dependent policy) they were responsible for enforcing.
But what happens when all that information is combined inside the agent’s working context with an unvetted document, an external service response, or a conclusion generated by another agent? The original security labels and access rules don’t necessarily carry forward in a way that preserves their meaning or makes them enforceable. Even if the metadata is retained, it doesn’t automatically tell you what the newly derived information represents or what can legitimately be done with it. You can end up laundering sensitive information through a completely authorized processing path, producing an unclassified or incorrectly classified result that traditional DLP controls may not recognize.
And now that information is in the hands of an agent that can act. In a conventional analytics pipeline, an incorrect combination might land in a reporting table or produce a misleading dashboard. That can certainly cause damage, but there was often a person involved in interpreting the result and deciding what to do next. In an agentic system, the composite stream may be connected directly to execution tools, APIs, and webhooks. A bad conclusion can trigger an unapproved financial transfer, corrupt a customer record, disclose confidential information to another party, or initiate a business process that should never have happened. The information doesn’t even need to leave the organization to cause significant damage. It only needs to influence the wrong decision.
Source of Truth?
This is also where the tech industry’s obsession with the single source of truth starts to look rather quaint. We’ve spent decades trying to consolidate information into authoritative repositories and systems of record, which makes sense when you’re trying to establish where a particular business record is maintained. But the fact that a record is authoritative in one system doesn’t automatically make every conclusion derived from it authoritative. A system of record is not necessarily a system of truth for every possible use of the information it contains.
Take a customer’s financial position assembled from account balances, pending transactions, external records, and recent communications. One source may be accurate as of this morning, another may contain information that hasn’t been verified, and a third may be authoritative for one particular business purpose but not for the decision the agent is currently making. The agent combines all three and produces a conclusion that another agent uses to make a decision. Which source is the truth? More importantly, is the conclusion actually valid for the purpose for which it’s being used?
Lineage, State and Attestation
This is where data attestation becomes important, and it’s quite different from simply knowing where the data originated. You need to understand what was verified, under which conditions, what authority was associated with the information, and whether those conditions are still valid when the resulting information is used. Lineage tells you something about where information came from and how it moved through a system. It doesn’t, by itself, establish that a conclusion is appropriate, authorized, or even correct.
Then there’s the problem of state. Traditional enterprise data management is heavily oriented toward persisted state, but information being processed inside an agentic system is constantly evolving. New evidence arrives, prior assumptions become invalid, permissions change, and the purpose of an operation may shift as the workflow progresses. An agent can delegate work to another agent that has different permissions and obligations. Information that was perfectly legitimate for one step in the process may no longer be legitimate for the next.
The challenge is that the processing state, information state, and authorization state all have to be considered together. You can’t simply assume that because a piece of information was valid and authorized at the beginning of a workflow, it remains so throughout every subsequent transformation and decision. And when something goes wrong, you need more than a collection of API logs and database access records to understand what happened. You need to be able to reconstruct the processing, the decisions, the context, and the authority under which those decisions were made.
Understand, Dissect, Disseminate with Prejudice
I’m not suggesting that enterprises abandon data protection at rest, database permissions, classifications, or any of the security infrastructure they’ve spent decades building. Those controls have legitimate purposes and aren’t going away. They are informative, but treating them as the solution to protecting information being processed continuously throughout an enterprise simply recycles the same assumptions that stopped us from cracking it in the first place.
You better be damn good at understanding, dissecting, and disseminating the composite stream, because the protection of information in an agentic environment has to account for its use, not simply its original classification. Some information needs to be sealed. Within those sealed packages, particular elements may need to be redacted or omitted. Other information can be released only in a minimized or coarsened form, and some operations need to be denied outright before an agent is permitted to proceed.
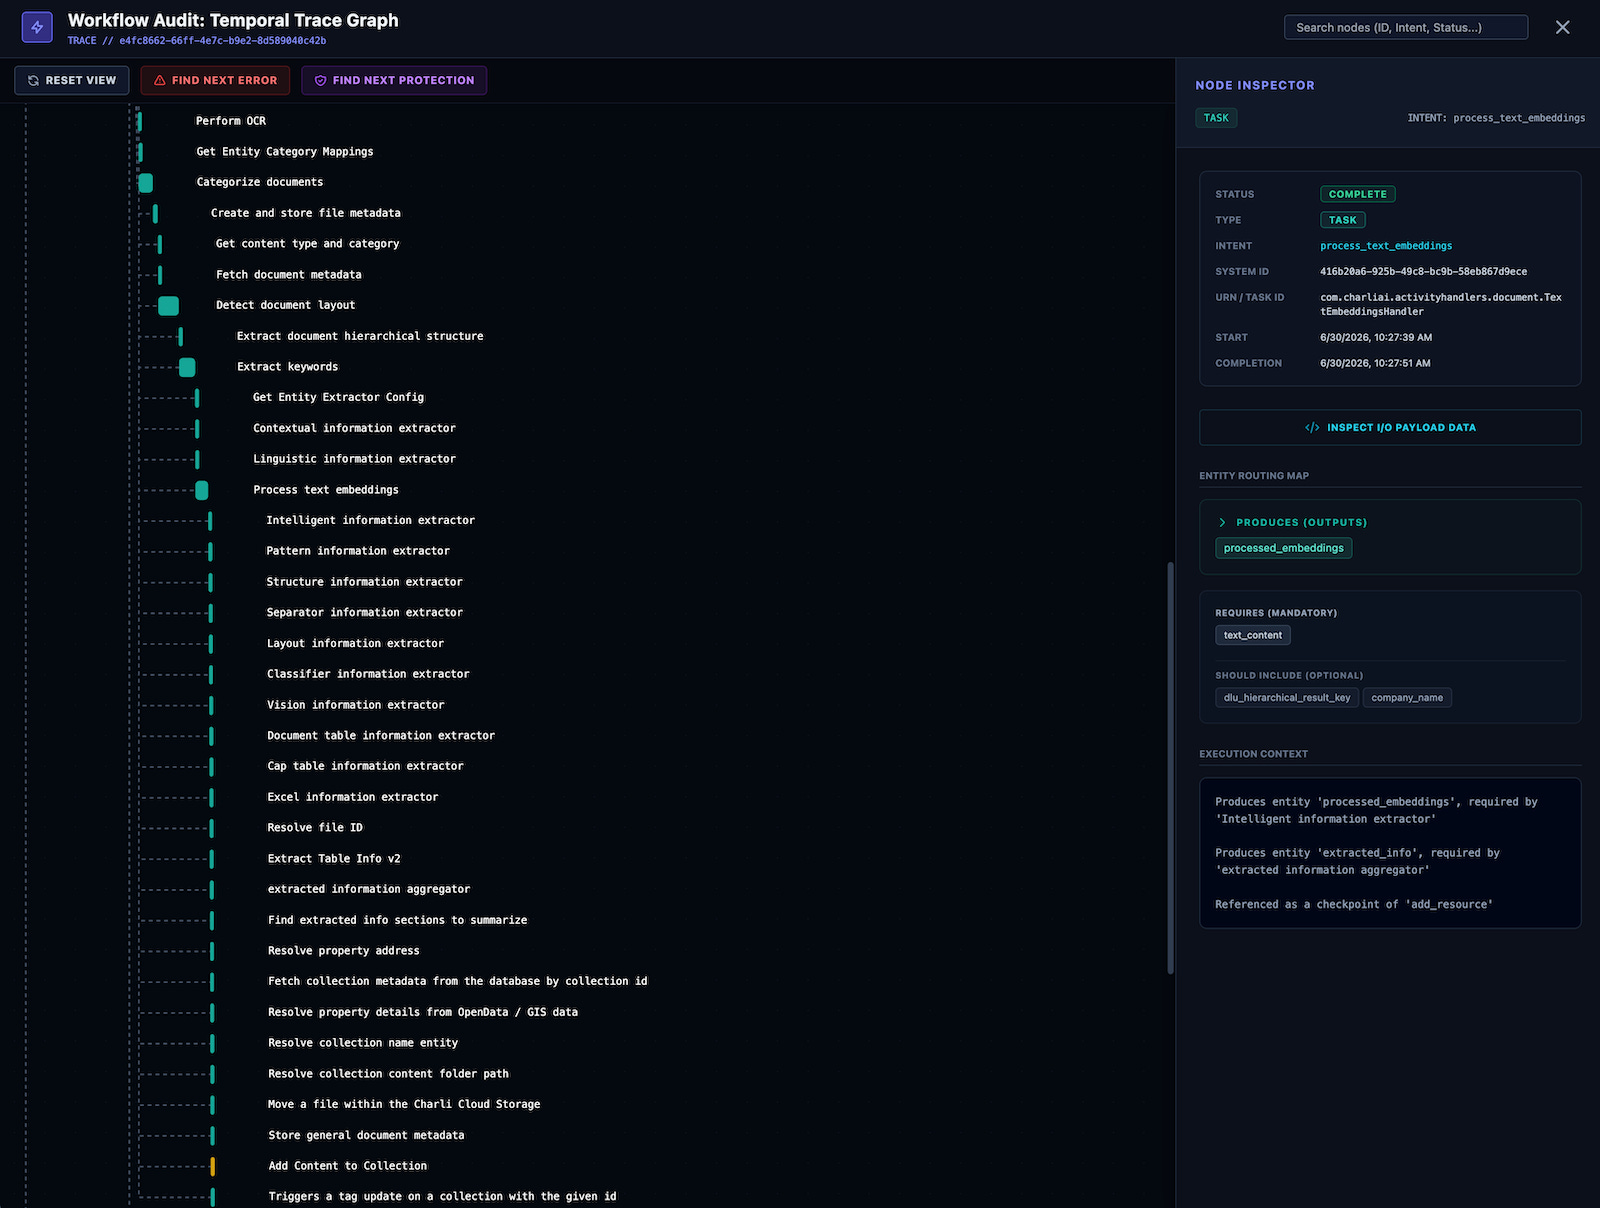
That means policy interpretation and enforcement can’t be limited to a permit-or-deny decision at the point of retrieval. There are obligations and conditions associated with how information can be processed, transformed, shared, and used. A policy might permit access to a customer record but require certain fields to be removed before the information can be passed to another agent. It might allow a derived risk assessment to be used internally while prohibiting disclosure of the underlying financial details to an external party. It might permit an agent to prepare a transaction but require additional authorization before that transaction is committed.
These aren’t particularly exotic business requirements. Enterprises have been dealing with variations of them for decades, generally with a combination of application logic, manual processes, and human judgment. The difference is that autonomous systems now need to interpret and enforce those conditions across distributed processing environments, often without a person sitting between each step to figure out what is appropriate. They also need to do it at machine-speed.
And the stream isn’t just what you feed into the model. It’s every outcome produced by every agent and model call, the intermediate conclusions, the tool responses, and the information passed between processes. The wrong data shouldn’t end up sitting in an agent’s scratchpad, leaking into a log file, being propagated into another context, or being exfiltrated through an otherwise legitimate integration. Nor should an agent be able to turn information it was authorized to read into an action it was never authorized to perform.
This requires an understanding of the information throughout execution, combined with the ability to apply controls while processing is actually happening.
What the Humans Were Doing All Along
I find it remarkable that we’re still having these conversations as though they’re entirely new problems. We’ve understood information processing, distributed state, authorization, and data integrity for decades. The underlying challenges didn’t suddenly appear because somebody connected an LLM to an API. What’s changed is the speed, autonomy, and complexity of the processing, along with the removal of much of the human interpretation and judgment that previously sat between information retrieval and action.
For years, people quietly resolved inconsistencies, questioned conclusions, checked whether something was appropriate to disclose, and decided when information was sufficiently reliable to act upon. Those decisions weren’t always formalized in application logic or documented in governance policies. They were simply part of how the business operated. Agentic AI is exposing how much of that judgment was implicit (tribal), and how little of it is actually represented in the controls we’ve built.
Yet the industry continues to respond with the technologies and disciplines it already understands. Data management companies want to manage more data. Security vendors want to inspect another gateway. Data scientists want cleaner datasets and better models. And enterprises are being told that once they’ve made their data AI-ready and connected it to the right platform, they’ll be ready to start automating their business.
If an enterprise is still struggling to organize, classify, and manage its underlying data, it has foundational problems that predate agentic AI by decades. But even an organization with exemplary data management can have enormous problems when autonomous systems begin processing information and making decisions. Having a clean, well-governed repository doesn’t guarantee that the information leaving it will be interpreted correctly, combined legitimately, or acted upon within the authority of the business. Yet we’re still applying the tools and thinking of data persistence to dynamic information processing, and then acting surprised when the controls don’t hold.
The Problem Is in the Processing
Data doesn’t exist inside an enterprise simply to be stored, classified, retrieved, or analyzed. It’s used to run the business. It moves between people, applications, processes, and now autonomous agents. Its meaning and permissible use depend on context, purpose, authority, and the decisions being made around it. That’s what we need to understand and control.
We’ve had forty years to learn the distinction, and I would have thought we’d be further along by now. Instead, we’re back to arguing about where to put the data, how to classify it, and which platform should own it, while autonomous systems are busy combining, interpreting, and acting upon it at machine speed.
And looking at the direction of much of the industry, I suspect we’re going to spend an awful lot more money rediscovering problems we should have understood a long time ago.