I wrote back in July about why AI observability was so critical, and I still believe that. But after a summer of conversations with enterprises, security teams and partners, I think the language itself is now holding us back.
Every serious enterprise is scrambling to get control over its AI and Agentic AI initiatives, and the entire concept of “AI Observability” has taken on new meaning. It’s no longer just about observing. It is about Active Surveillance because, as I said then, no one wants to run blind when agents are operating autonomously.
So, what is the difference?
Surveillance is the active, deep and continuous monitoring of AI and agent processing, actions, and behavior in real-time, not just passive observability or cursory examination. It is no longer sufficient to simply observe the inputs and the reasoning process of a model, or reactively review the inputs and outputs from chatbots. Let’s be honest, that type of watching has been table stakes for decades in the tech world and falls under the general domain of monitoring and debugging tools. With AI and Agents, you must now actively surveil the environment, the container, the actions, the data ingress, the data egress, the triggers, the identities and the authorizations as they occur in real-time.
If you refer back to our Executive Briefing on what you can learn from Command and Control, surveillance is much more action oriented than the passive observing of what happened within an environment. Enterprise operations requires active surveillance.
“We gave the machine authority. Therefore, we must continuously determine whether it remains qualified, authorized, and safe to exercise that authority.”
That’s a substantially different architecture.
There is also a big difference in monitoring and surveillance in the real-time inferencing realm versus the contained environment of static model training. These two cannot be equated and the techniques, technology, methodologies and people will vary significantly.
Surveillance moves out of the roost of data scientists who simply want to understand model behavior or techies that want to debug. Surveillance over AI is now a corporate strategic responsibility. It is there to prevent breaches and exposures, ensure agents do not go rogue, and enforce the strict policies that govern the company.
The shift to AI automation in the enterprise requires active surveillance not observation in passing. This level of surveillance requires a different mindset (a shift in perspectives), one rooted not just in risk and quality assurance, but also in operational liability and operational rigor.
Industries such as energy, aerospace, manufacturing and heavy equipment operators have long relied on Operation Centers and Master Consoles to maintain real-time safety and control. It’s how they sleep at night. In today’s white collar world, enterprises are waking up to the realization that they are now operating semi-intelligent agents that need that exact same level of operational surveillance.
Contracts being reviewed automatically, transactions being conducted behind the curtain, suppliers being selected with minimum oversight and even orders being fulfilled just-in-time by an agent.
Telemetry is Not Instrumentation
If you want to cut through the signal-to-noise ratio and see actionable intelligence, you need to start thinking Instrumentation. Some may think this simply comes down to telemetry and that instrumentation and telemetry are synonymous with each other. But that’s simply not the case. Telemetry is important but its just the rudimentary signalling and there’s a lot of it out there. If you really want to make sense of what’s going on, you need to synthesize the vast amount of noise in the telemetry raw data.
The key to instrumentation is giving operators the right information at the right time to actually operate the system. It is the intelligence behind the instrumentation that alerts operators not just to when something breaks, but before it breaks or before it goes sideways. A lot of tools track tokens but that’s just akin to tracking the dollar bills leaving your wallet. Instrumentation lets you know if you are getting the value back from those bills … where you’re spending fruitlessly versus what’s giving you the biggest bang for your buck.
What does this look like in practice?
It all depends on whether your AI strategy is about tracking the chatbots your employees are using, or you want to monitor a handful of agents in an experiment, or you’re looking at real enterprise workflows:
-
Chatbots and chat-with-data: These are human-based interactions with a model. They effectively “dump-and-answer,” so observability is typically left to firewalls and gateways. Even in these cases, you need to switch to surveillance in order to understand where the retrieved data comes from, understand the retrieved data semantically, and even decide if you want to restrict and protect data both in and out of the organization. Surveillance is more than just a gateway as even in these cases, cross-chat interactions have a bigger attack surface.
-
Single Agents: Agents are similar, but because they take autonomous action you need to pay more attention, and you need to know exactly what they are doing inside their processing. This is generally done via telemetry “cooked up” by developers and spewed out into logs. It’s fine for one-off debugging, but massively dangerous for operational integrity, and like chatbots, the cross dependencies are an inherent risk as are the cascade problems for upstream and downstream processing.
-
Enterprise Workflows: Real enterprise surveillance requires a holistic approach across many systems, many agents and many data sources. You need to closely monitor the upstream, the downstream, the data feeds, the agent internals, the system internals, and the cross dependencies. If you think you’ll hand off an enterprise workflow to a god agent to magically handle the end-to-end you’ll be in for a rude awakening. Enterprise workflows are complex and instrumentation across this is equally complex.
There is a natural reaction to rely on logging as a primary source of information, but this quickly becomes inadequate as log stitching has proven to be an arduous, fraught, and brittle undertaking. This is not intended to take away the value of logs but to highlight the signal-to-noise problem as well as the inability to trace steps, track dependencies, understand timing triggers as well as provide detail on the ingress and egress of every agentic request (not what logging was designed for).
To get to this level of surveillance requires a Control Plane Architecture that includes an Agentic Information Bus, Agentic System Monitors, and an immutable persistence layer. These all work in concert to provide the signalling flow and the traceability required for operations. Logging in this case is ancillary and supportive, but not primary. The approach is not unlike one would find in the industrial and aerospace worlds … even your car has a similar approach.
The Standards Gap
The security industry has successfully modelled system-level security in traditional tech environments through standards bodies and organizations including NIST, IETF, OASIS and others. This includes well-established architectural approaches for policy administration, policy information, policy decisioning and policy enforcement. You also have Zero Trust designs that go back years and that still apply today. However, these standards are incomplete when it comes to the agentic world because you now have to deal with semantics and semi-intelligence.
Agentic workflows are autonomous and involve one or more agents with identities, authorizations and mandates. Notice how I said mandates? That was intentional. These agents have delegated authority to perform actions, and those actions can propagate automatically across your organization in order to streamline, optimize and improve operations.
That sounds grandiose, but it’s that very autonomy and semi-intelligence that crosses you over into a new realm. With automation, you are now dealing with OT-like operational requirements on top of traditional IT systems. OT, or Operational Technology, has always been subjected to a harder level of operational rigor because the consequences of something going wrong can be immediate and severe.
A traditional application does what it is programmed to do and is considered (for the most part) deterministic. It will always do what it has always done (again for the most part). If an error or discrepancy or deviation crops up, the developer debugs it and releases a fix. Not so in the agentic AI realm. An AI agent decides what to do at runtime based on a little thing called context. That context is an ever changing set of instructions and data, and you may not anticipate or realize what you’re going to get in return. This is all the more true if you use a frontier model where the vendor can switch the model without you realizing it. This makes real-time surveillance far more mission critical. Every interaction within a workflow needs a surveillance monitor, and you need to track the output from one step right into the input of the next and all the way down the line. This may seem extreme, but enterprise operations requires it just like the OT world.
So what are the standards missing?
In this world, you need Orchestrated Control over every agent and every agentic task. If you lack orchestration, you lack the temporal telemetry needed to determine cause and effect. Essentially, you cannot separate the Governance Control elements from the orchestration itself. They are married. The alternative is that you will inevitably rely on a never-ending exercise of “log stitching” that is fragile, error-prone, and entirely insufficient for security audits never mind active surveillance.
The ‘Smart’ Reality of Agents and Models
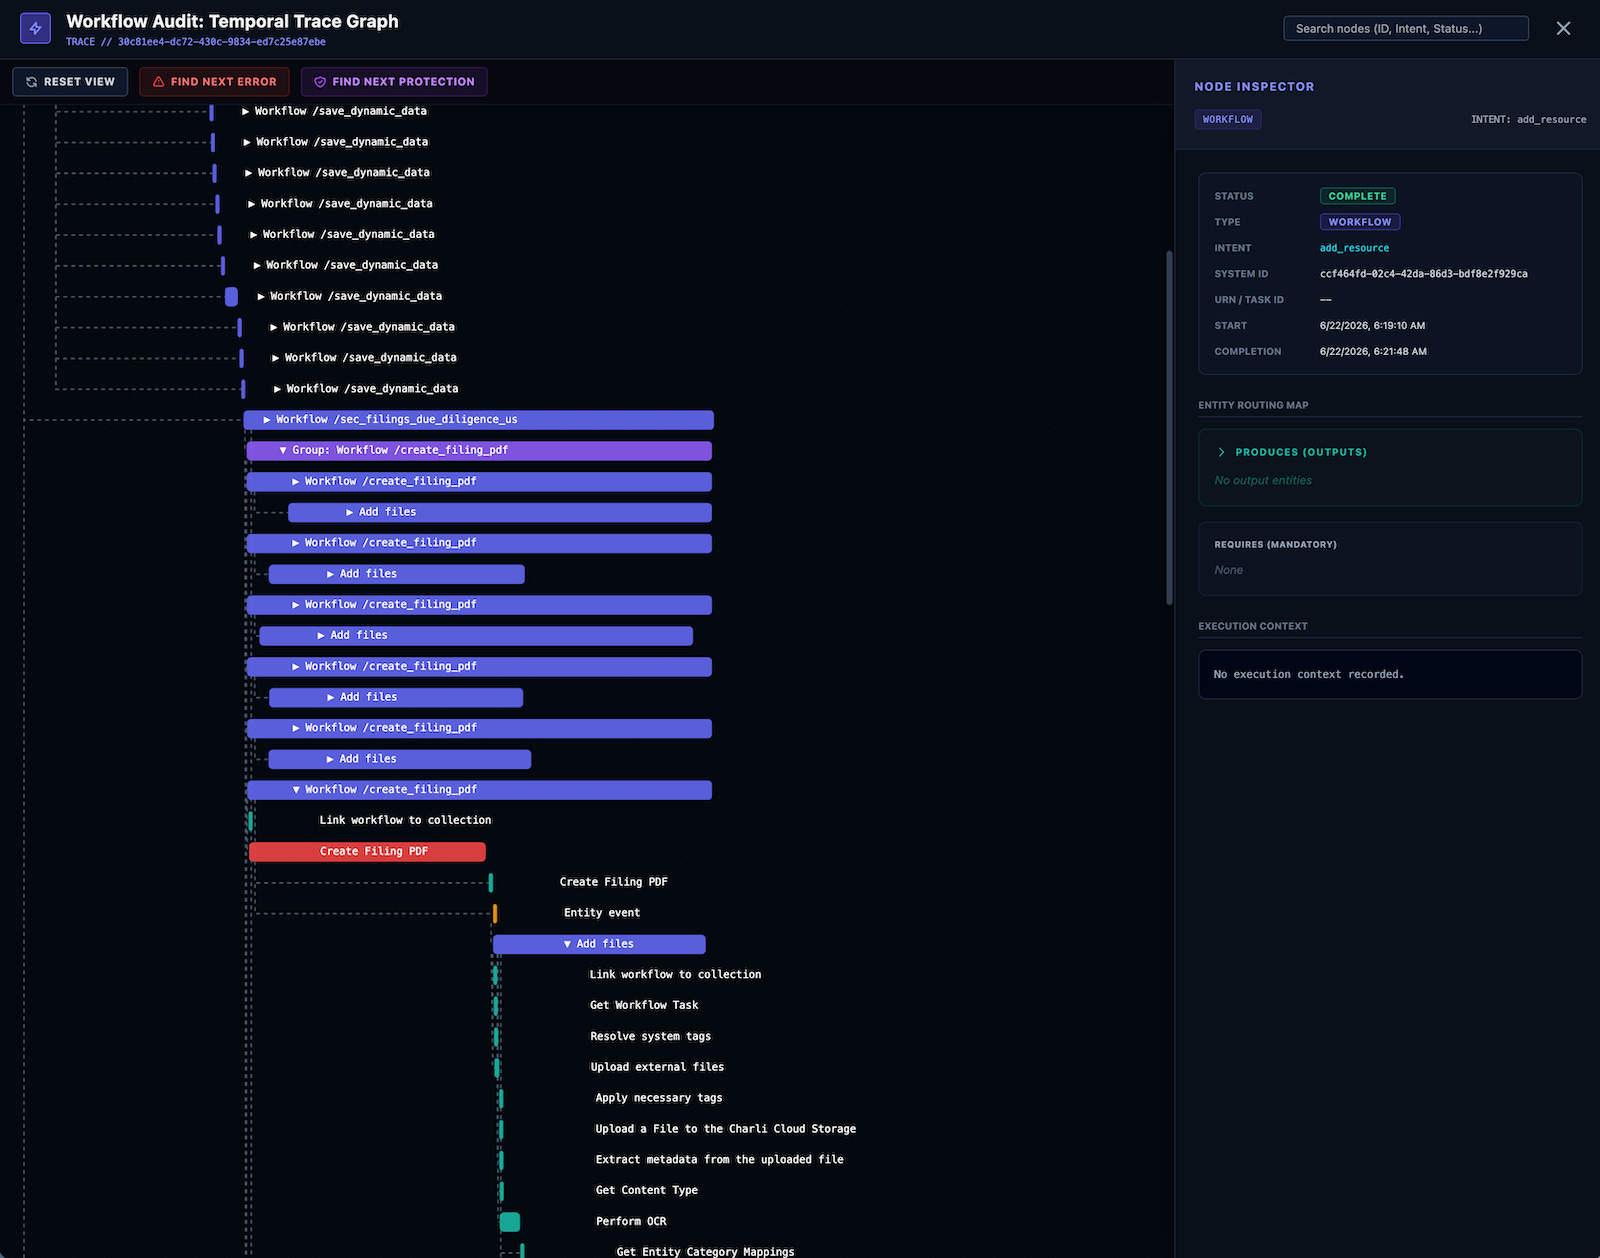
Orchestration ensures you capture all interactive points within a workflow, including the ingress and egress from models, as well as the model’s reasoning and retrieval processes. Ingress monitoring to an agent (and its integrated LLM) alone is insufficient, as both agents and models will frequently reach out to external systems and/or the internet to augment their reasoning.
This direct linkage to external data sources, whether they be in-company or not represents a crucial liability risk. It can poison, infiltrate, exfiltrate, and inject data or cause agents and models to drift. If the agent can write back to a cache, a scratchpad or an internal database, or even take action on this data, the risk escalates rapidly … to the point of being untenable. For a secure operating environment the data augmentation approach that these agents and models rely upon must be equally governed and surveilled.
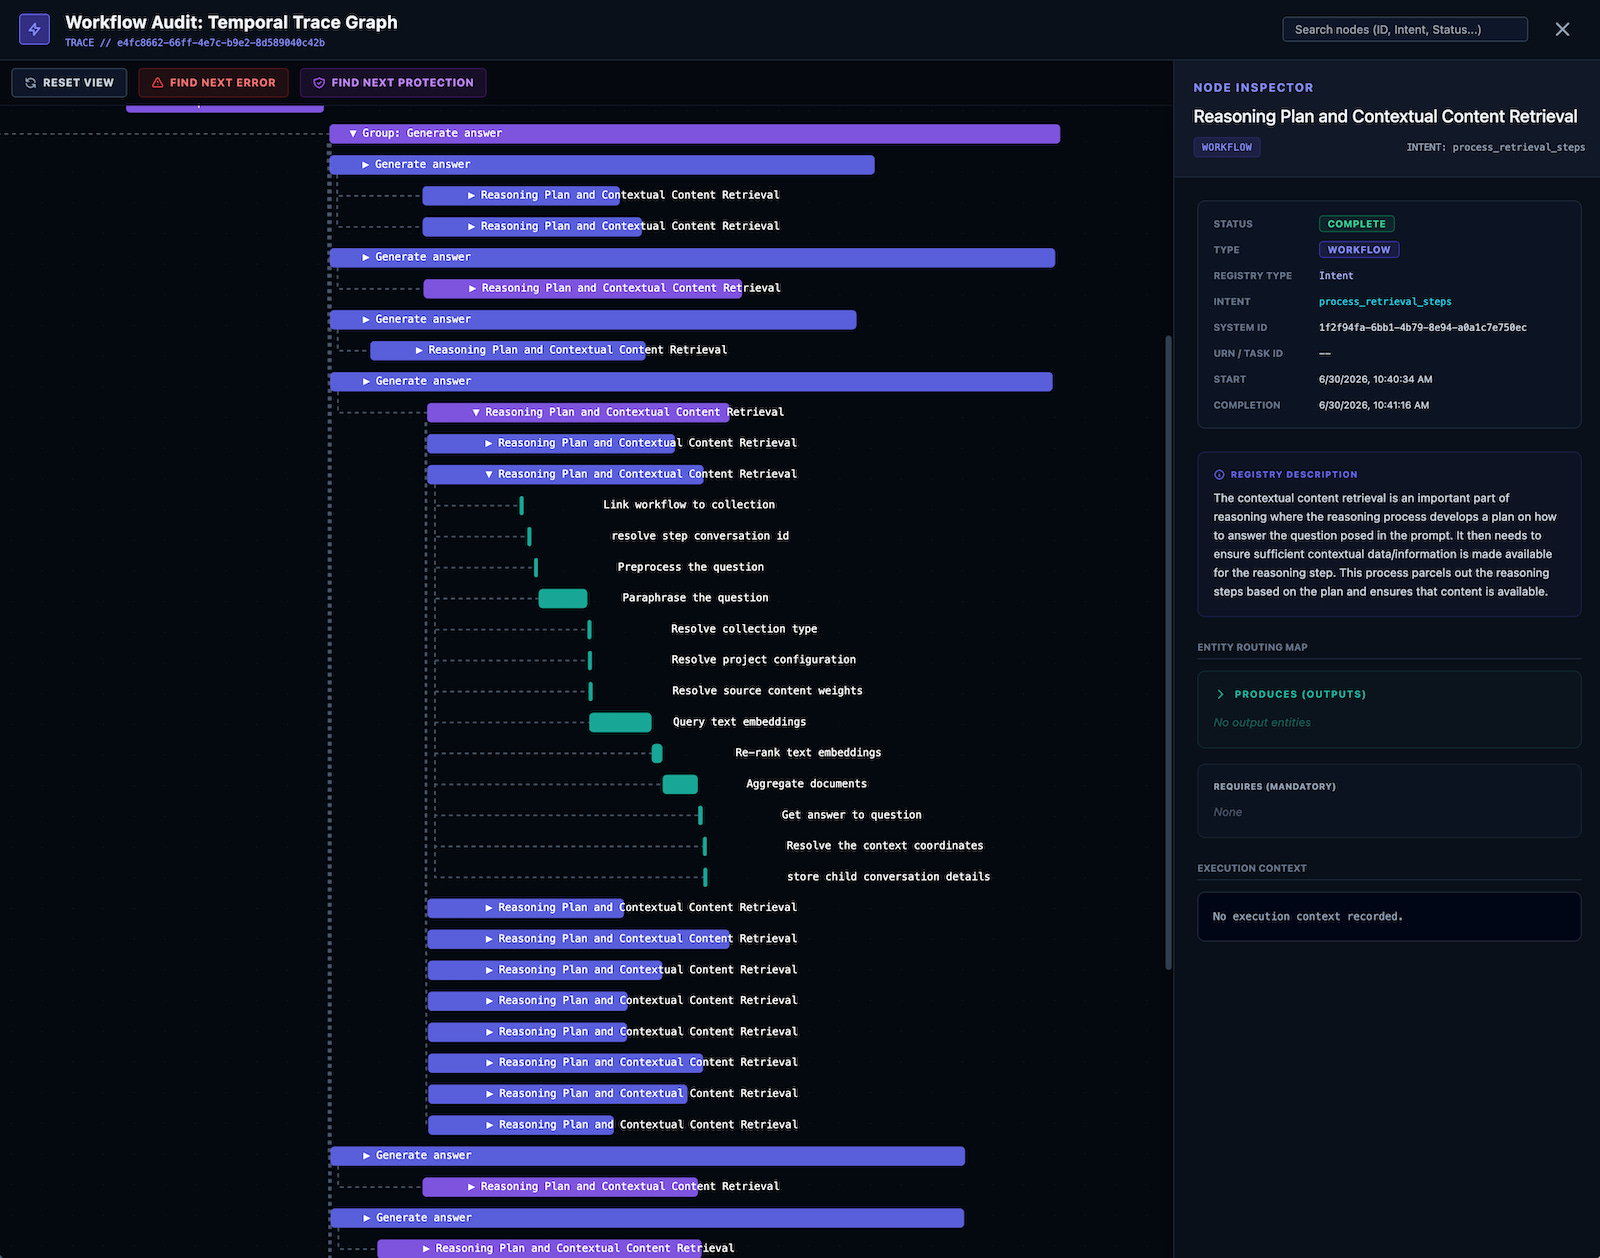
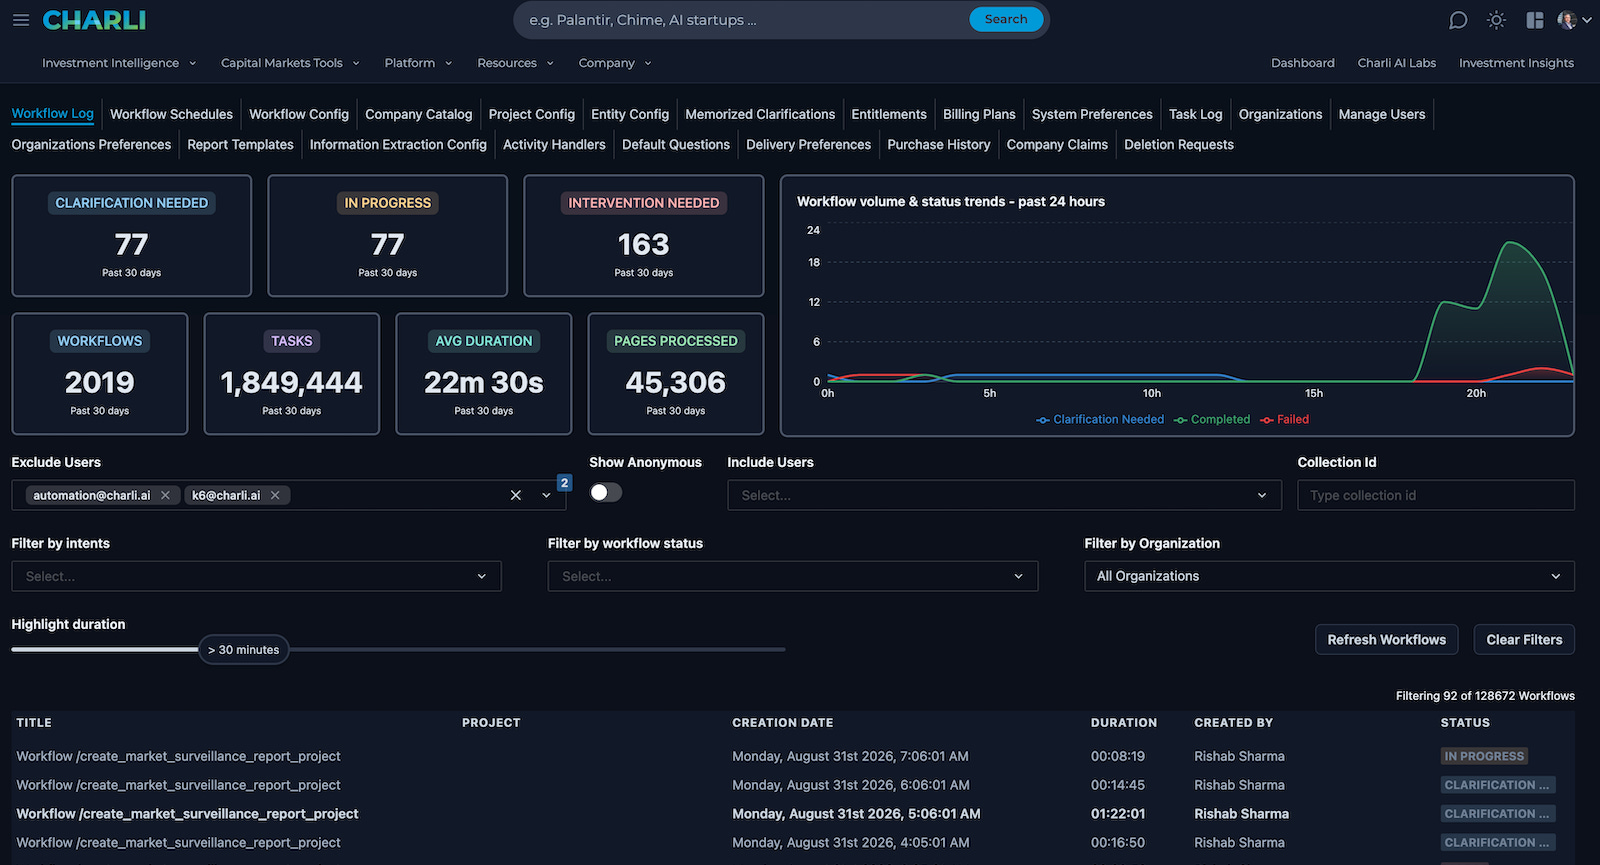
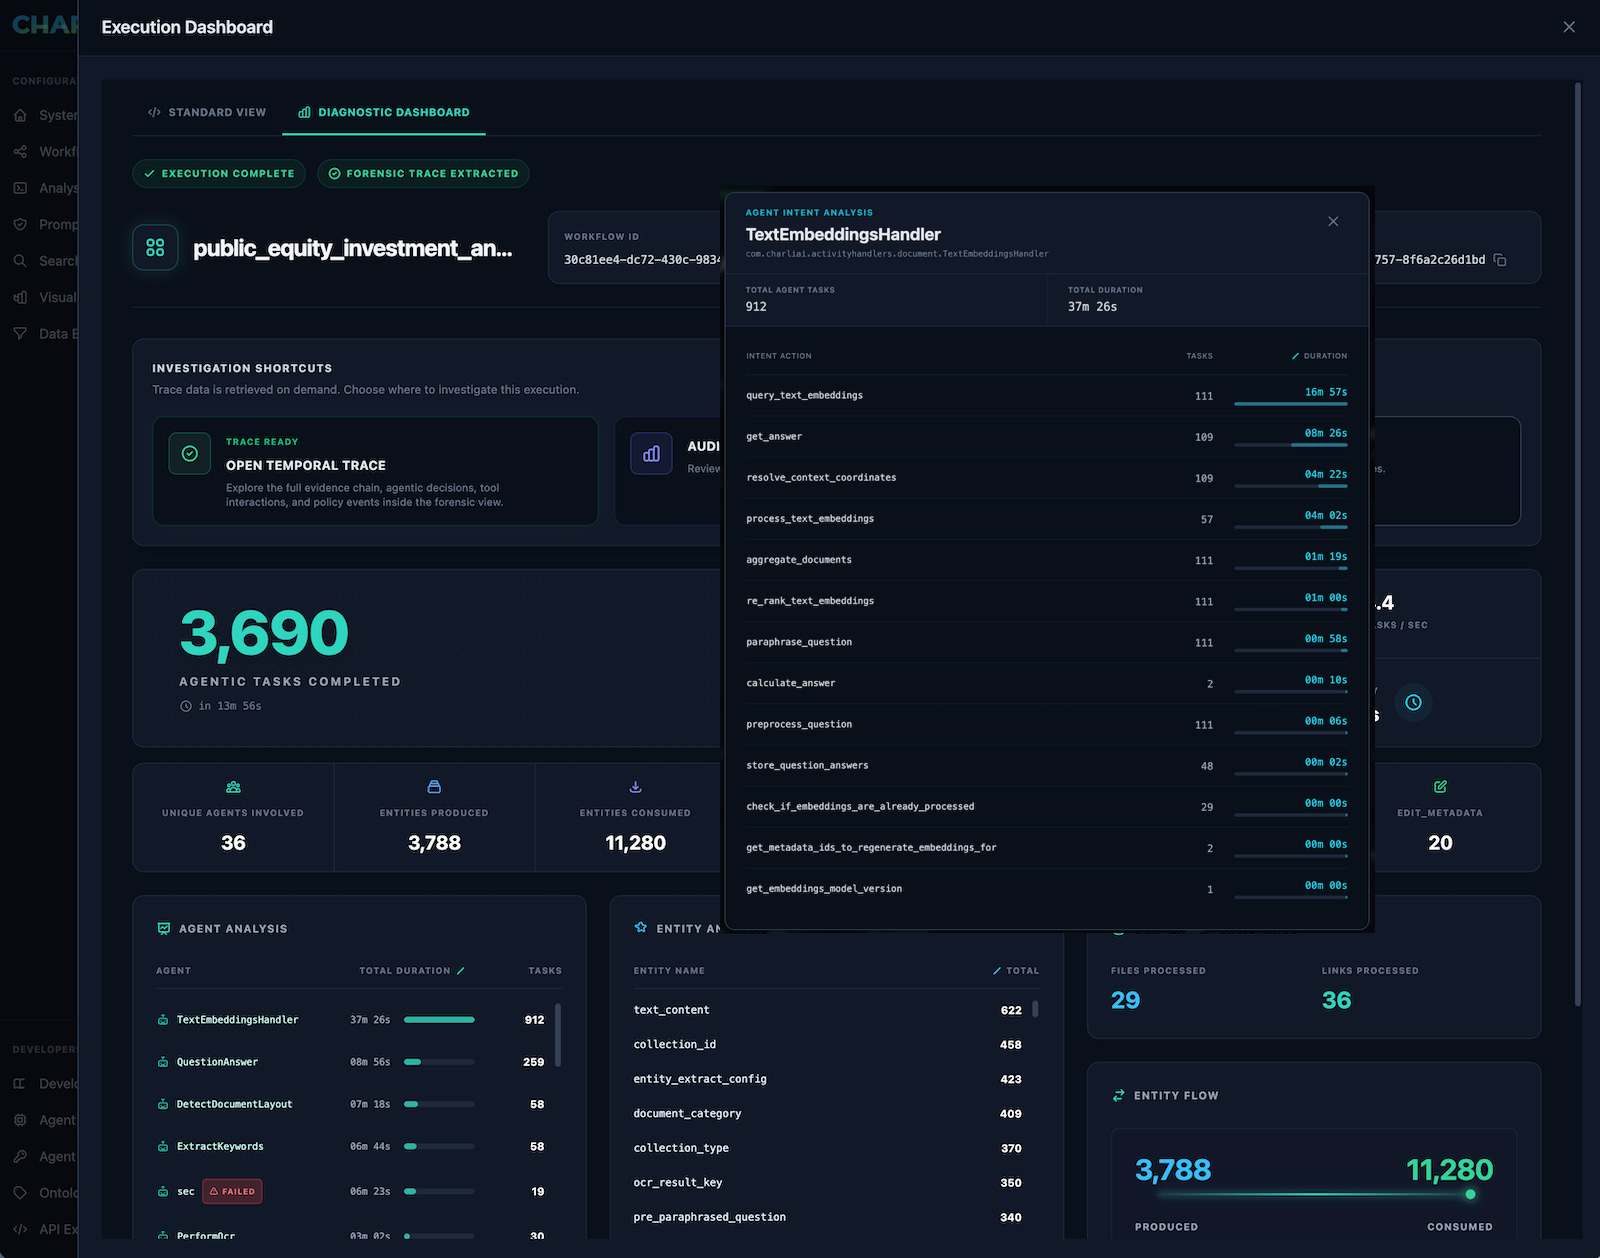
As shown in the live screenshot, you must have significant visibility into everything that precedes and supports the model, the model’s internal processing, model interactions, and the agents handling of the model outcome. Even with frontier models, the actual outcome goes through further post-processing before anything is released to the user or downstream agent, and you need visibility into that post-processing layer.
MCP and an MCP Gateway you might ask? That gets you only so far. Contrary to what others might call the nervous system of LLMs, they are no such thing. They are simply API calls to a model and you need surveillance on this just as much as the model operation itself.
Getting There
The Control Plane Architecture is obviously required for this to work, but you also need the system monitors to get the real signals to the Control Plane and into the central (or distributed) governance console. The system monitors should implement strict telemetric standards and augment that with the necessary lineage, identity, authorization, and metadata necessary for temporal tracing. Likewise the system monitors can communicate data ingress and egress for further lineage. System monitors can be implemented as proxies, eBPF filters, VPC firewalls, network sniffers, and a combination of all of the above to track … as long as they normalize and decorate to the standards required by the Control Plane.
That normalization and decoration is key, because this is where the semantics either work for you or against you. Normalization of the telemetry is an important element of finding the signal in the noise and therefore your best chance is to ensure effective normalization and decoration at the source. In CharliAI, we call this the handler and we never leave it up to the agent nor the developer to curate the signal.
Enterprise-grade Active Surveillance is the foundation of any successful agentic AI strategy. Without it, you’ll never know where to place your decision gates, your guardrails, or your policy enforcement points.
At this point, this is where I end this article … in a very atypical fashion.
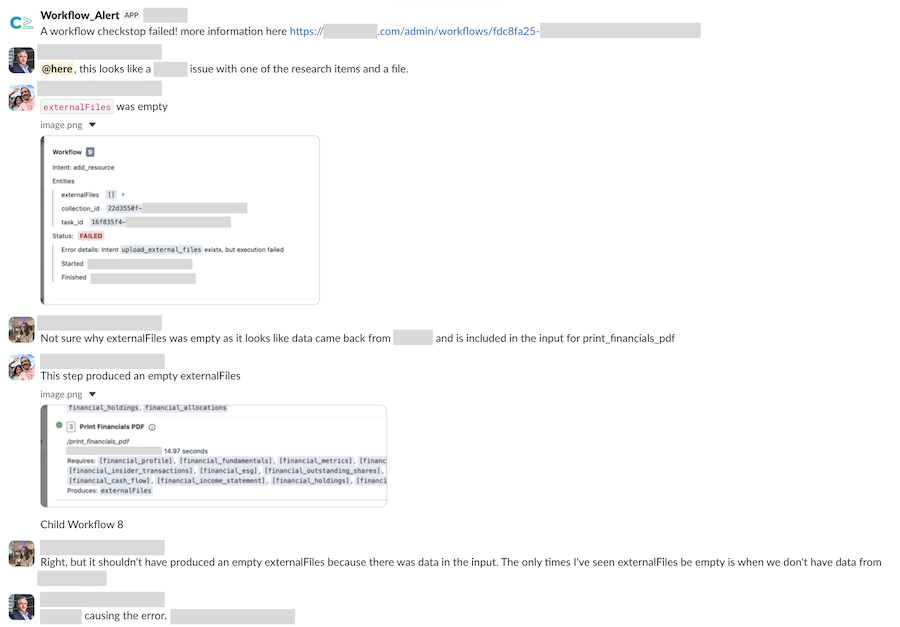
Below is a real screenshot from an internal Slack exchange and escalation from just a couple of weeks ago. The Control Plane trapped and stopped an in-flight workflow because one of the agents involved in a transaction failed to meet the minimum outcome standard. Not everything failed. Just this one small element in a single agent out of 33.
One agent returned what looked like a valid response, but it caused a downstream agent to fail its operation. The AI Control Plane stopped the workflow immediately and requested human intervention through the channels monitored by the operators.
Out of 33 agents and thousands of tasks, the system pointed the operators directly to the workflow and the exact problem. Within minutes, the dependencies were identified, inspected, and the root cause isolated. Agent 8 impacted Agent 9 and, if not caught, the issue would have propagated downstream as hallucination, drift, or both. The cascade problem was stopped dead in its tracks.
I could’ve used a Get Smart comedic moment here, with Agent 86 disastrously impacting Agent 99. But alas, this one is Active Surveillance for real.